Prague Based
Global reach

Voice AI Agent

Year

2026

Services

Voice AIElevenLabsSvelteKitWebSocketsLatency ProfilingTraefikDockern8n

Summary

Talk to a company's in-house AI agent in natural Czech, and interrupt it like a person. I built the voice layer on top of the existing chat, cut response time by 39%, and gave the client hard data for their telephony decision.

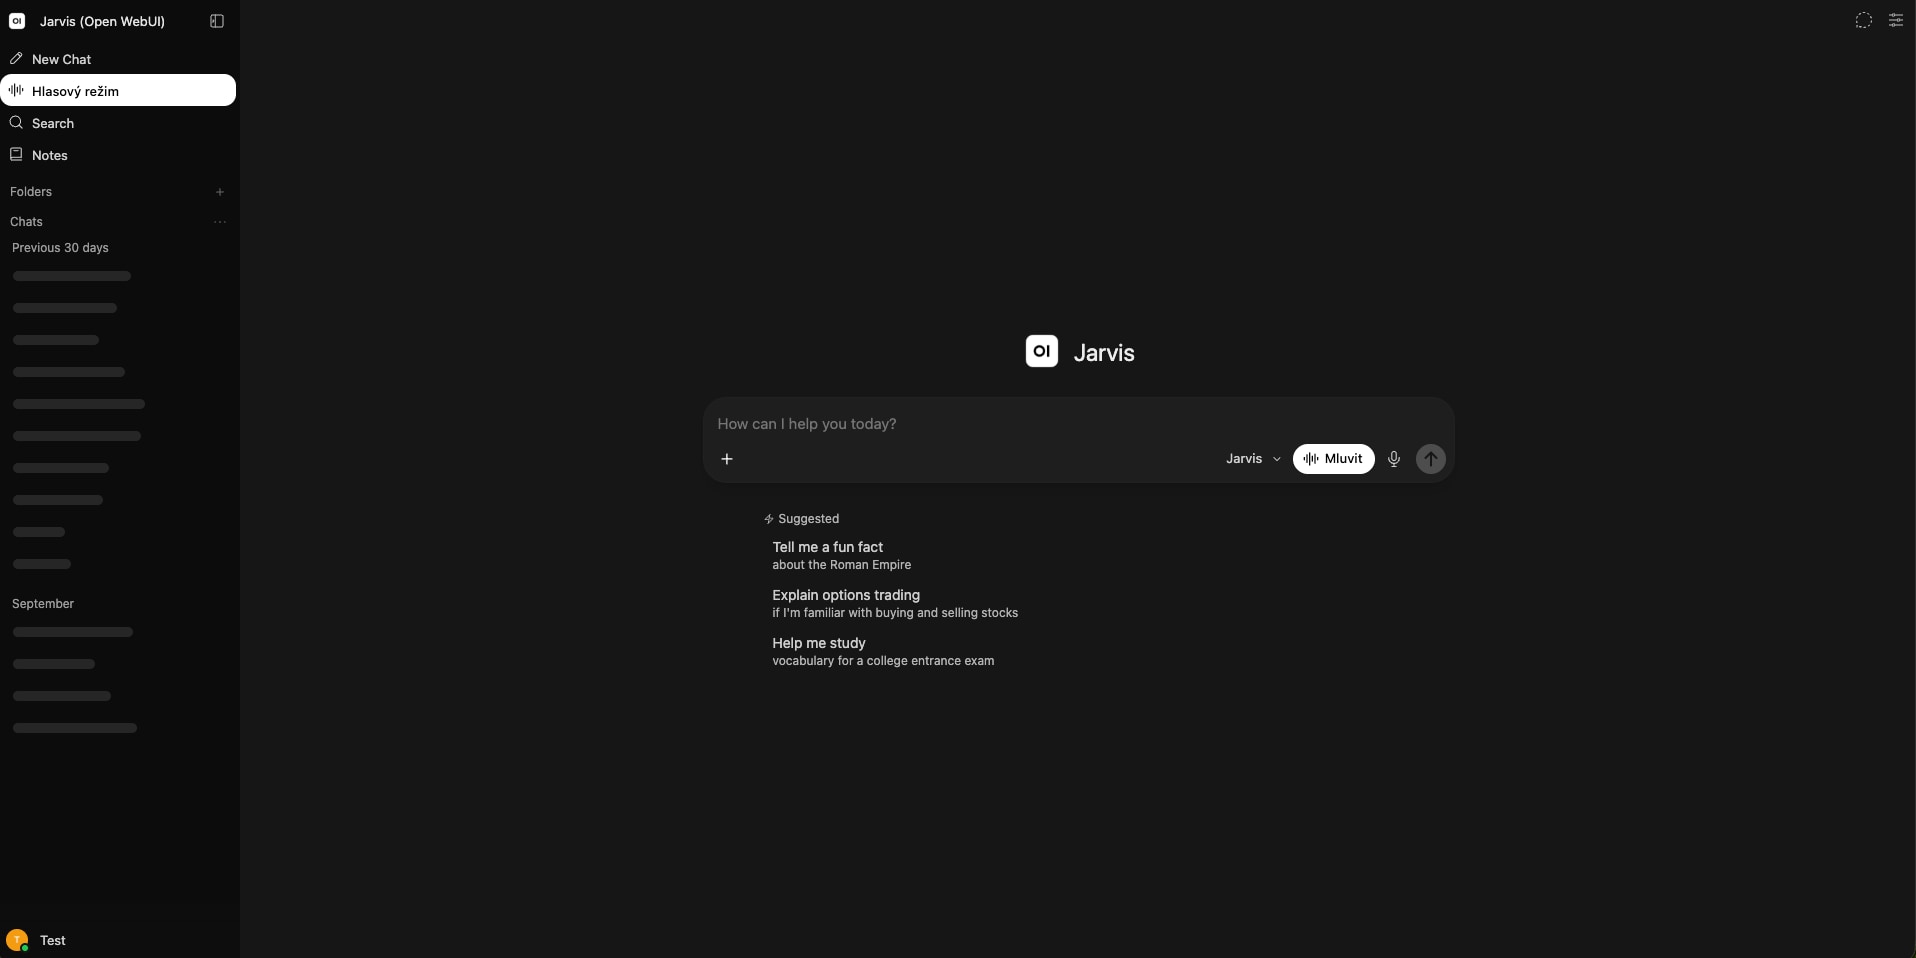
The company chat with a “Mluvit” (Talk) button in the message field and a “Hlasový režim” (Voice mode) entry in the sidebar
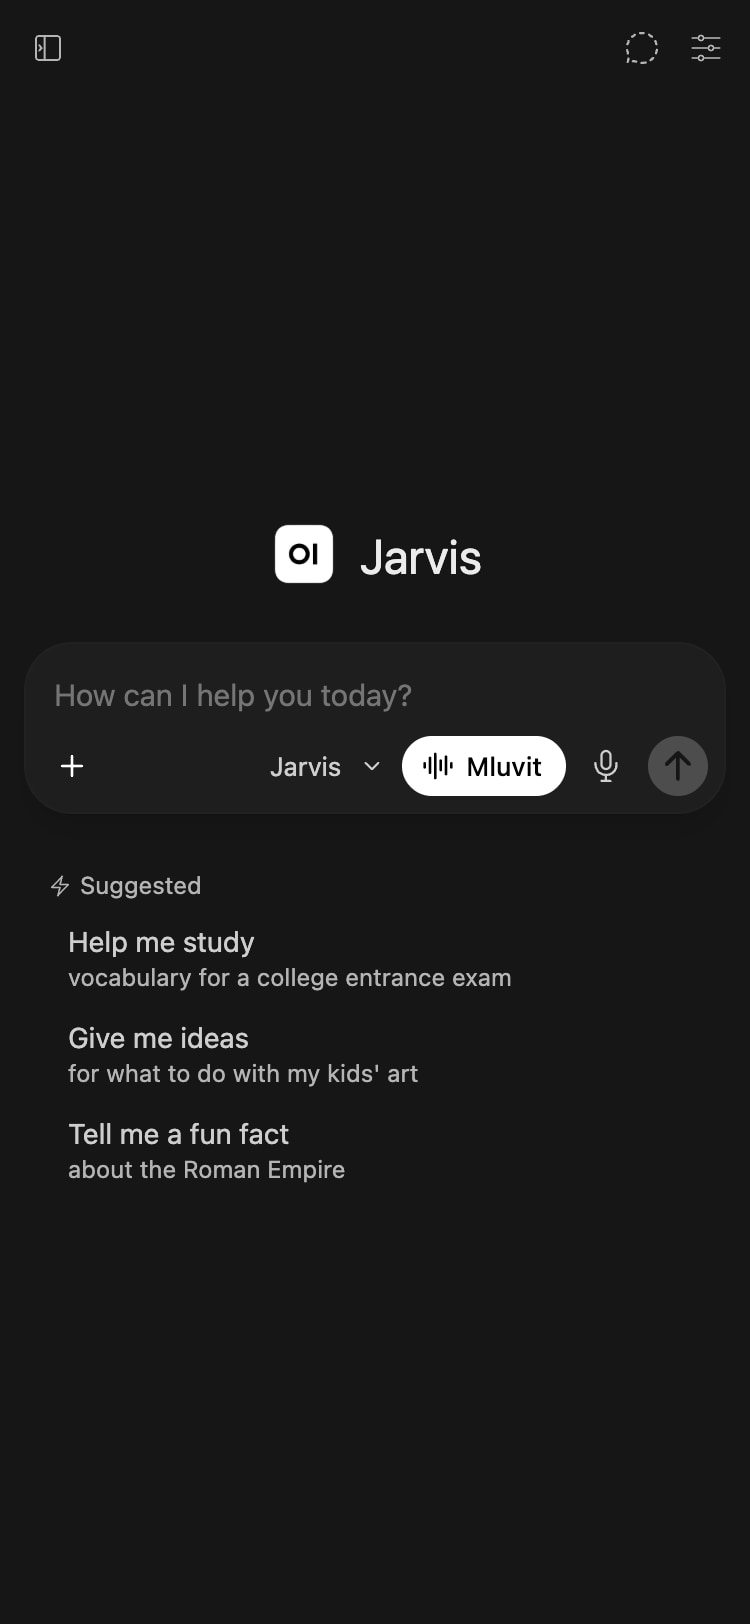
Mobile view of the chat with the “Mluvit” (Talk) button in the message field
Live in the client’s chat · desktop & mobile“Mluvit” (Talk) in the message field, “Hlasový režim” (Voice mode) in the sidebar

Measured first.
Then made it fast.

The voice provider wasn't the bottleneck. The agent's prompt was.

−39%

End of speech to first audio — 6.4 s down to 3.9 s

32 → 4 tools

Prompt 65% smaller: voice gets only the tools it needs

~4.70 Kč

All-in cost of a 2.5-minute call. Model cost cut by 68%.

Architecture

A thin voice layer. The agent stays untouched.

Browser
Mic & speakerShort-lived token onlyInterrupt any time
audio
ElevenLabs
Speech EngineSpeech-to-textText-to-speechTurn-taking
text
Client VPS · Docker · behind Traefik
Voice service
Built by meSvelteKit · Node · WSHolds the keysStreams the replySpeaks per sentenceCzech pronunciation
SSE
Hermes agent
OpenAI-compatible APIUnchangedTools, memory, skillsInternal network only
MCP
n8n tools
via MCPRevenueLeague results…
01Keys stay homeThe browser only gets a short-lived token.
02One loginReuses the chat’s sign-in. No new user database.
03Agent untouchedPrivate network only, config unchanged.
04No new portsBehind the existing proxy under /voice.

Latency breakdown · median per turn

6.4 s → 3.9 s

From the user going quiet to the first sound back, measured live.

End-of-speech detectionService + agent to first sentenceSpeech synthesis & transport

Hover or tap a segment

BaselineShared agent, all tools
6.4 s
Lean instanceVoice-only agent, 4 tools
4.1 s
Streaming tweaksSentence chunking tuned
4.3 s
Speculative turnReply prepared before you finish
3.9 s
0s1s2s3s4s5s6s7s8s

The telephony decision

Build on our layer, or switch to the off-the-shelf one?

For phone calls, the client could switch to ElevenLabs Agents. I ran both paths with the same voice, model and questions, twice each.

Speech Engine + our serviceElevenLabs Agents, custom LLM

End of speech → first audio · hover a point

General question
4.1 s
4.4 s
Phone number & amount
3.8 s
3.3 s
Tool call: revenue
11.6 s
8.5 s
Tool call: league results
10.1 s
13.5 s
“What time is it?”Hit the 4 s timeout → retried, agent restarted from zero
12.4 s
36.0 s
0s10s20s30s40s
6.2 vs 6.0 sMedian without the time question. Same speed.
~$0.08/min~3.7 credits per second of call in both paths. Same cost.
4 sDefault wait for a custom LLM’s first token (max 15 s). Tool calls failed silently.

Recommendation

Switching works, at the same speed and cost. It goes live once:

  • Tool calls reliably under 15 s
  • Give the agent the current time
  • A filler line while it works — “One moment, let me check…”
  • A stable endpoint instead of a tunnel

The test caught the hidden timeout before customers on the phone did.

Side quest · local model on the same VPS

Can a small model run on 8 CPUs and no GPU?

For background jobs like sorting e-mail and pulling out amounts and company IDs. 15 test messages, 4 fields each.

ModelAll 4 correctMedian / msg
Gemma 4 E2BQAT
15/15
5.8 s
Qwen 3.5 2BQ4_K_M
10/15
4.8 s
Qwen 3.5 4BQ4_K_M
10/15
11.5 s

Long input · Gemma 4 E2B · time to first answer

25s
40s
82s
172s
396s
1.3k2.1k4.2k8.1k16.1k

Input tokens. Answers stayed correct at every length; speed is what breaks.

Verdict

Gemma 4 E2B is right for background jobs, not for chat.

Also shipped on the engagement

  • 01Agent identityThe agent became “Jarvis” in chat and voice, with global instructions documented and verified.
  • 02Files round-trip planHow the agent can hand back edited files, and why Word/Excel formatting can’t survive.
  • 03Ops hygieneBackups, rollbacks and a port audit on a shared production server.

Want a voice agent for your business?

I add voice to existing AI agents, chats and internal tools, and measure it until it's fast and cheap enough to use every day.

Get in touchSay Ahoj! 👋Email copied! ✈️